Paper · 2026
The Metanym Game: An LLM Benchmark Without Ground Truth That Rises With the Models It Measures
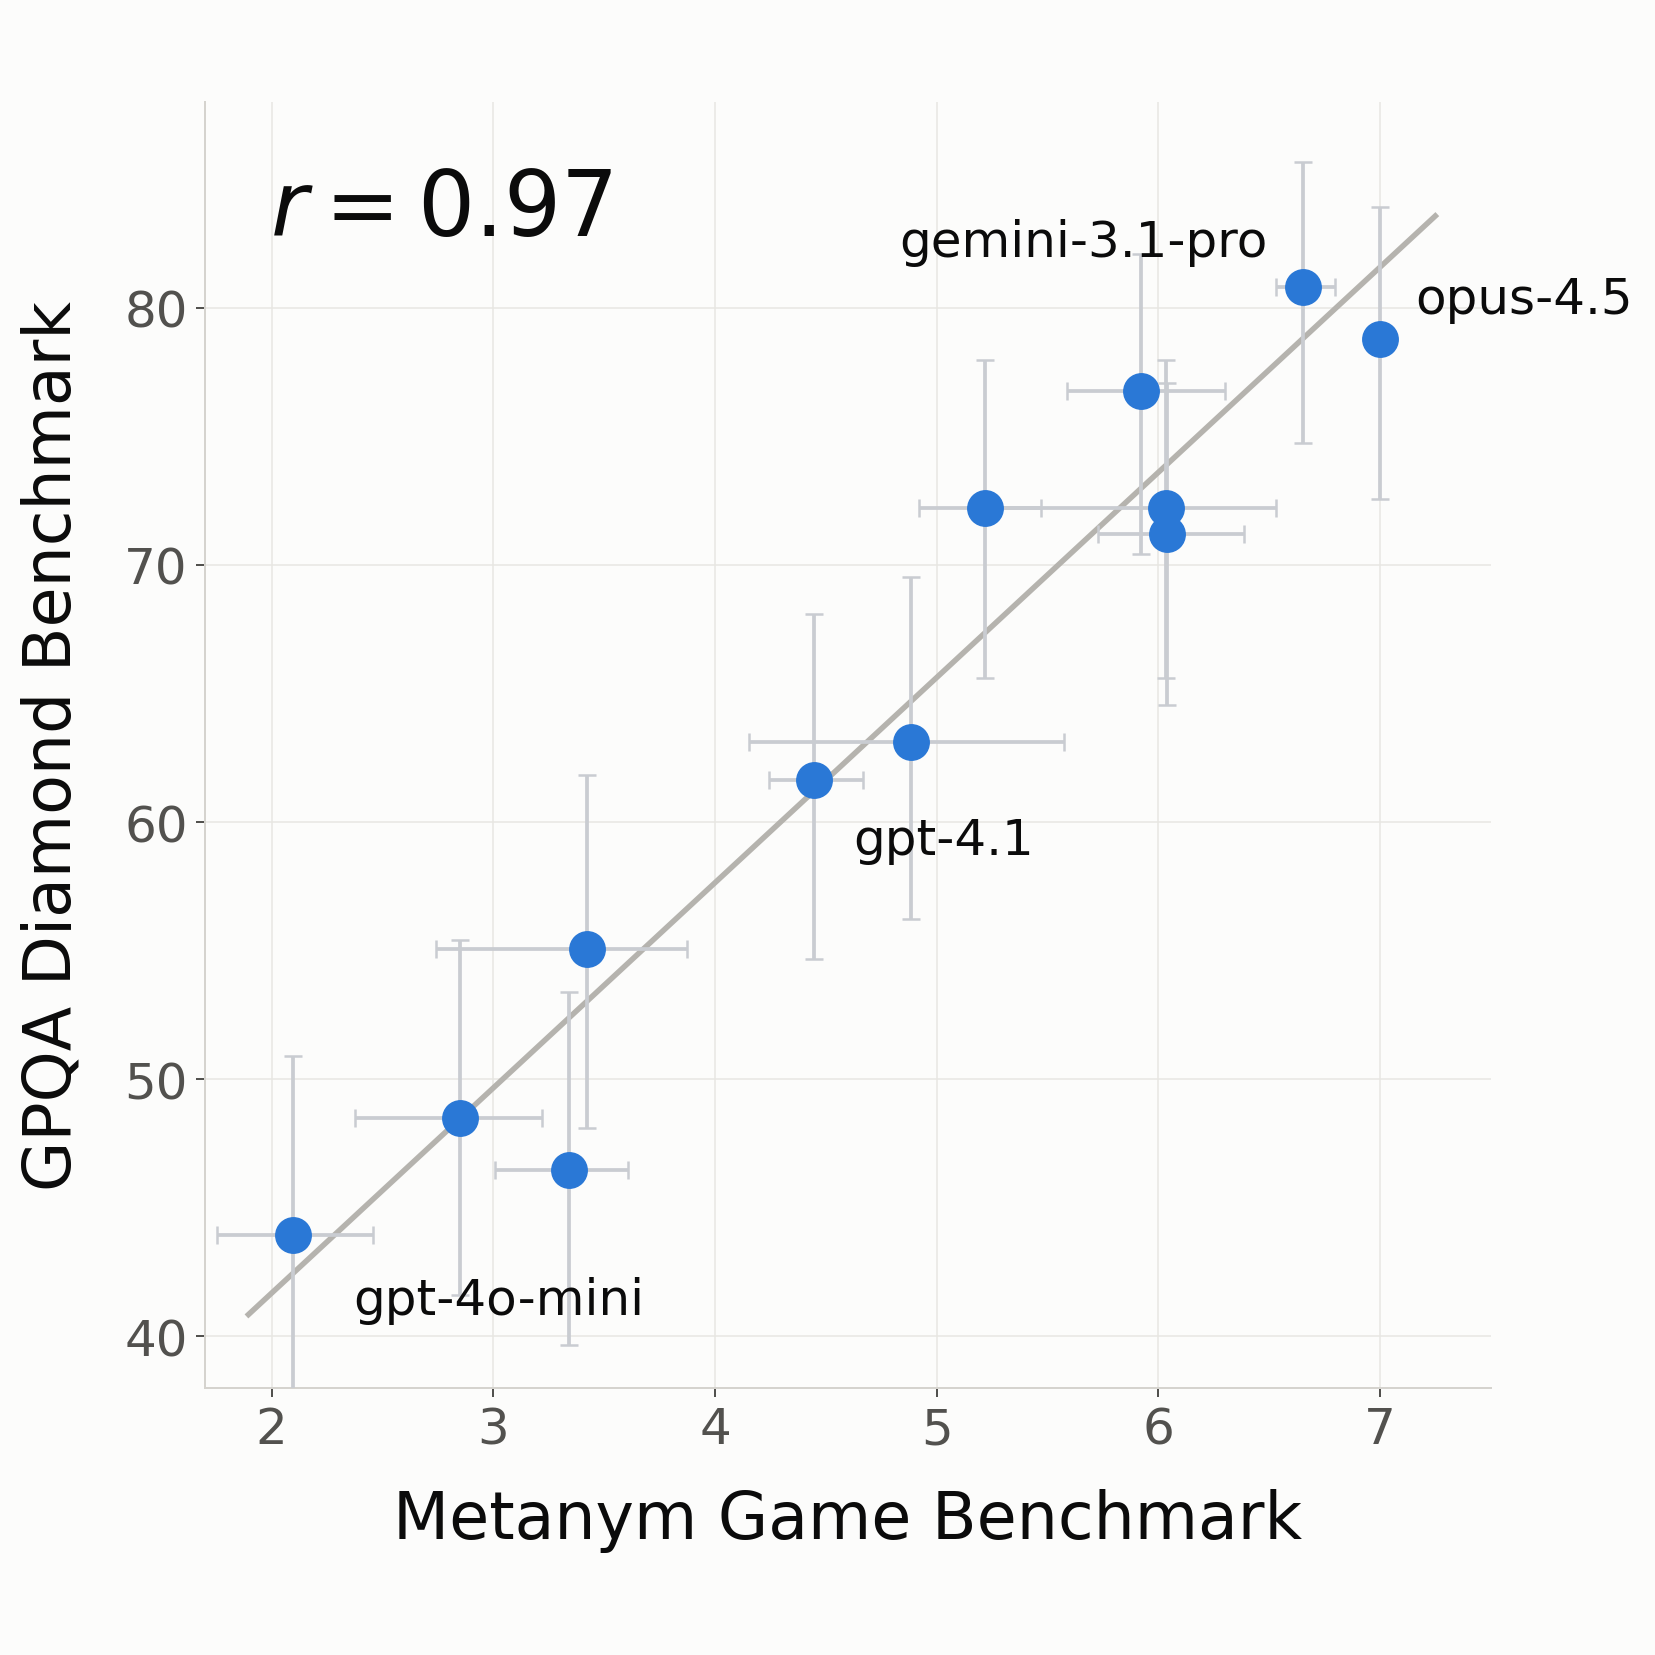
A benchmark that is fully self-contained, needs no ground truth, and rises with the models it measures. Language models compete at making analogies and subjectively grade one another; nothing enters from outside. The benchmark reproduces GPQA Diamond, a keyed benchmark of expert-written questions, at r = 0.98, audited for a leak and found clean.