Paper · 2026
The Metanym Game: An LLM Benchmark Without Ground Truth That Rises With the Models It Measures
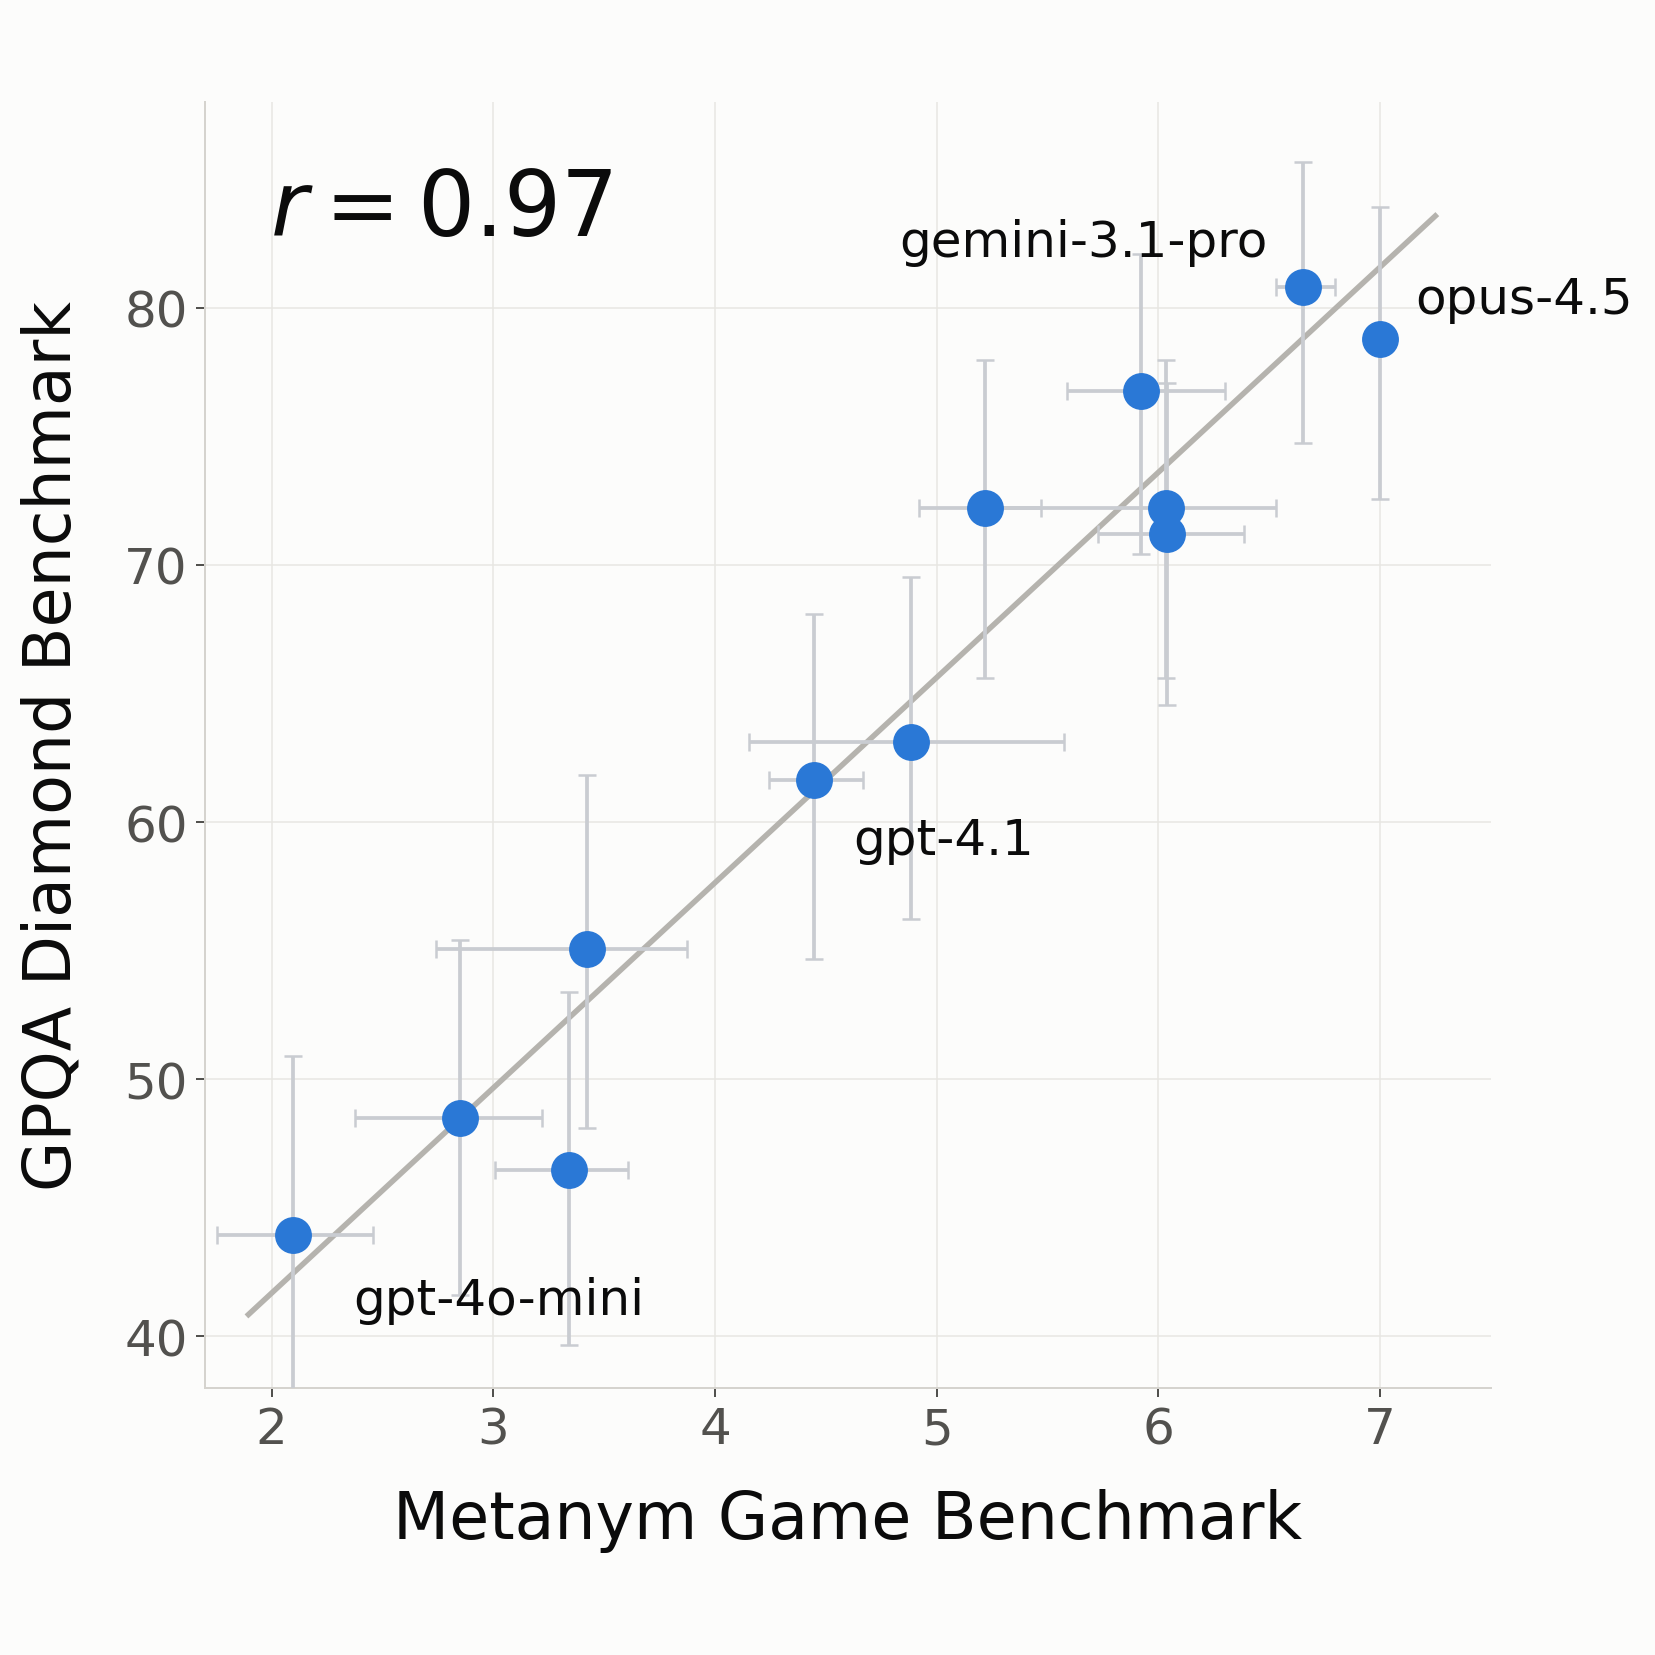
A benchmark that contains its own ground truth. Language models compete at generating analogies and subjectively rate each other; nothing enters from outside. Play interweaves eight kinds of intelligence. Provocatively, it correlates at r = 0.97 with GPQA Diamond, an established benchmark of expert-written questions — a different method entirely. The correlation was audited for a leak and found clean.